

The ability of large language models to generate computer code from natural language (NL) prompts has revolutionized the programming domain. Most contemporary models however can only generate code for seen libraries and function calls, and struggle when they encounter any of the new libraries or functions that are constantly being introduced. A human programmer facing such a challenge would typically research and retrieve user manuals and other relevant documents to familiarize themselves with the new library/function — could LLMs be taught to do the same?
In the new paper DocPrompting: Generating Code by Retrieving the Docs, a research team from Carnegie Mellon University and Inspired Cognition presents DocPrompting, a novel NL-to-code generation approach. Tasked with generating code to unseen functions or libraries from an NL intent, DocPrompting retrieves corresponding code documentation to enable the model to learn to perform the task.

DocPrompting is inspired by programmers’ use of manuals and documentation when encountering unseen/unused functions or libraries. The approach first learns to retrieve relevant documents from an external documentation pool, then learns to generate code using prompts based on the information it gleaned from the documents.
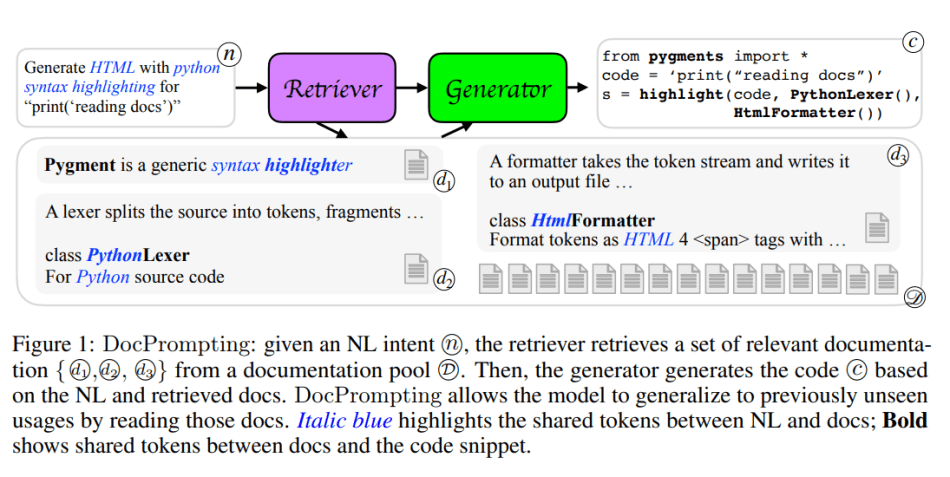
The documentation pool can be regularly updated with new content to enable DocPrompting to generate unseen and unused functions and libraries without requiring any costly retraining of model components. DocPrompting is also a general method — it can be applied to any programming language and is not bounded to the underlying neural model, and can be instantiated with any base retriever and generator.


In their empirical study, the team evaluated DocPrompting on two NL-to-code tasks and benchmarks: shell scripting and Python programming. In the shell scripting task, DocPrompting consistently improved on the base model; while In Python programming, CodeT5+DocPrompting performed exceptionally well on unseen functions and achieved a 1.65 BLEU score improvement over the state-of-the-art result.
This work opens a promising new direction for the evolution of code generation. The team says that, to their best knowledge, DocPrompting is the first approach to explicitly and effectively leverage documentation for NL-to-code tasks.
The code is available on the project’s GitHub. The paper DocPrompting: Generating Code by Retrieving the Docs is on arXiv.
Author: Hecate He | Editor: Michael Sarazen

We know you don’t want to miss any news or research breakthroughs. Subscribe to our popular newsletter Synced Global AI Weekly to get weekly AI updates.
Interesting approach using retrieved documentation to help code models handle unfamiliar libraries instead of relying only on patterns from training data. The part about improving generation for new function calls feels especially practical, and I could see a similar retrieval idea being useful in other AI tools too, including video workflows like Best Free AI Video Generators in 2026 (Real Limits Tested).
The idea of retrieving documentation on demand rather than hoping the model memorized everything during training feels like a much more scalable path for code generation, especially as new libraries appear constantly. The fact that DocPrompting can be updated without retraining is a big practical win. I wonder if similar retrieval-augmented strategies could help other generative tasks that struggle with unseen inputs, such as stereo sound video generation where models often need to adapt to novel prompts or styles on the fly. It’s a clever crossover worth watching.
“Horn OK Please” art apne aap mein ek poori culture hai — aur music uska hissa hai. Yeh site us classic road vibe ko ek jagah collect karti hai: horn ok please truck wala music, jab bhi nostalgia trip chahiye, ready.
Great breakdown of DocPrompting. The idea of retrieving external docs instead of relying only on trained patterns is a smart way to handle unseen libraries — kind of like how humans look up manuals. It also got me thinking about how much Unicode and text formatting matter in everyday online spaces. For lighter, more creative text needs, I’ve been using Tiny Text Generator, a free tool that turns your words into small caps, superscript, and subscript Unicode. Perfect for styling usernames or captions on Instagram, Discord, and TikTok. Definitely worth a try: https://tinytextgen.com
Interesting read — DocPrompting reminds me how important external context is when generating code for unfamiliar libraries. It’s a bit like how I use my own character generator to explore new identities for stories or DnD campaigns: having the right reference material makes the output far more creative and accurate. If you’re ever looking for a fun way to brainstorm RPG or writing characters, check out my free generator at randomcharactergenerator.org. Nice to see research pushing models to reason with docs, just like humans do.
This is really interesting! I’ve always found it tough when LLMs hit unfamiliar libraries. It reminds me of how I’d search for answers on Choicer Voicer when I was stuck on a game mechanic. This DocPrompting approach sounds like a smart way to give models that same research capability.
It’s fascinating how DocPrompting addresses the LLM’s struggle with novel functions by mirroring human research habits. I’m curious about the overhead involved in maintaining and updating this external documentation pool; is there a point where the retrieval mechanism itself becomes a bottleneck? For managing complex creative projects, I’ve found that having access to a suite of image tools, like those offered by a suite of image tools, can really accelerate the ideation phase, especially when visualizing different conceptual directions.
It’s intriguing that DocPrompting’s retrieval mechanism prioritizes relevance. I wonder how it handles cases where multiple documentation snippets are equally relevant, or if ambiguity has been a significant issue during development. The ability to update the documentation pool without full retraining is a crucial efficiency gain. For managing creative asset pipelines, I’ve found that having access to PixBulk bulk generator can significantly streamline processes when dealing with large volumes of product images.
The paper’s approach of using retrieval for code generation is a clever way to tackle LLM limitations with new libraries. I’m curious if there’s a risk of the retrieved documentation being outdated or incomplete, potentially leading to subtle bugs in the generated code. For managing my own AI video generation projects, I’ve found that having a robust platform like Open Sora AI helps streamline the entire workflow.
The idea of retrieving documentation to ground LLMs for code generation is quite elegant, especially for those tricky unseen functions. I’m curious about the computational cost of that retrieval step itself, though – is it a significant overhead compared to the generation? For tasks requiring a lot of visual content, I’ve found that having access to a simple video tool like a simple video tool can really help in quickly staging different concepts.
The idea of retrieving documentation on demand rather than expecting models to memorize everything during training feels like a much more scalable path for code generation, especially as new libraries appear constantly. The fact that DocPrompting avoids costly retraining is a big practical win for keeping tools current. This retrieval-augmented approach makes me wonder if similar strategies could help other generative tasks that struggle with unseen inputs—even something like music recognition, where a model needs to adapt to unfamiliar tracks or genres without prior exposure. songspot.co It’s a clever crossover worth watching, and I’d love to see how this generalizes beyond code.
This research on documentation retrieval is fascinating. It reminds me how much AI is evolving, much like how I now use this tool for turning an image to video
This research on documentation retrieval is fascinating for developers. It reminds me of how I use tools to convert video to frame extraction
The core insight here—that LLMs should retrieve documentation the way programmers do—feels obvious in retrospect but is genuinely smart. The 1.65 BLEU improvement on unseen Python functions validates that this isn’t just intuitive; it actually works. What’s particularly clever is making the documentation pool updatable without retraining, which means the approach stays relevant as libraries evolve. I use image converter for converting image formats between projects, and similarly appreciate tools that adapt to new requirements without constant maintenance overhead.
Interesting approach using retrieved documentation to help code models handle unfamiliar libraries. DocPrompting’s retrieval step feels practical for improving generation on new function calls beyond just training patterns.
The paper’s focus on relevant documentation retrieval is well-motivated. Grounding generation in docs should especially help with version-specific or evolving libraries.
The Inspired Cognition angle on DocPrompting adds industry relevance. Using retrieved documentation to guide generation feels directly applicable to IDE assistants.
The comparison to baselines without retrieval clearly shows the benefit. DocPrompting demonstrates that relevant docs can significantly improve code correctness.
Retrieving relevant documentation before generation could also help with explaining code, not just writing it. The DocPrompting framework seems extensible.
The focus on relevant docs rather than generic context is key. DocPrompting’s precision in retrieval likely drives the generation gains.
DocPrompting’s approach to code generation via documentation retrieval is a solid step toward more trustworthy AI coding tools for unfamiliar APIs.
The CMU-inspired method of improving code generation by retrieving docs aligns with broader RAG trends, but tailored well to the code domain.
Interesting approach, and the results on relevant documentation improving generation suggest prompt engineering plus retrieval is a powerful combo for code.
DocPrompting’s retrieval of relevant documentation before code generation is a practical pattern that could be adopted in many dev tools quickly.
Overall, DocPrompting is a thoughtful contribution. Using retrieved documentation to improve generation for unfamiliar libraries addresses a clear limitation in current models.
The paper’s approach to dynamically retrieving documentation for unseen functions is quite insightful. I’m curious if DocPrompting has been tested on documentation sets that are known to be incomplete or contain errors, and how it might handle such scenarios. For my own projects, having a robust text-based music composition generator has been invaluable for quickly exploring melodic and lyrical ideas.
The notes around bleu score improvement over the state-of-the-art stood out to me because they give the post a clearer takeaway than a simple overview would. I appreciate when an article leaves a few concrete points to come back to after the first read. Free AI Image
DocPrompting’s retrieve-then-generate loop is a nice parallel to how a human actually learns an unfamiliar library: you follow references, jump between doc pages, and only then write the call. What interests me is that retrieval quality is really a graph problem — the retriever is only as good as how well the documentation is cross-linked and indexed, so a stale or poorly linked docs pool caps the whole pipeline regardless of the generator. That link-traversal instinct is underrated as a skill, and honestly the most enjoyable way I’ve found to practice it is a bit of a detour: Wikipedia link-racing challenge, where you hop from one article to another using only in-page links. Oddly good training for thinking about retrieval paths.
DocPrompting’s retrieval of external documentation to handle unseen libraries is a clever parallel to how human programmers consult manuals. I’ve seen the same pattern work well in gaming communities: players often rely on curated wikis to understand new mechanics, similar to how DocPrompting pulls relevant docs. For instance, the Slayers 2 community maintains a detailed Slayers 2 clan tier list that aggregates roll odds, breathing styles, and patch updates—essentially a domain-specific retrieval system for game data. It’s a good reminder that the retrieve-then-generate approach can be adapted beyond code to any knowledge-intensive task.
I enjoyed reading every word of this. Keep publishing great content!
DocPrompting’s approach of retrieving relevant documentation to improve code generation is a smart way to ground models in real APIs. It’s exciting to see retrieval-augmented methods spreading. Similar retrieval ideas could even help tools like an AI photo enhancer pick better restoration strategies.
Being able to update the documentation pool without retraining is the practical detail that stands out here. I would be interested in a test where several versions of the same API are present: a relevant-looking page can still be the wrong version. I maintain a Slayer 2 wiki, and even that smaller reference problem needs clear game names and update context so a trainer route is not confused with one from a similarly named game. It would be useful to see retrieval evaluated on that kind of near-match error as well as missing documentation. Does the paper separate retrieval failures from cases where the generator misuses the correct page?
The ability to update the documentation pool without costly retraining is a significant practical advantage. However, how does the system handle situations where multiple versions of the same API exist within the documentation, potentially leading to confusion? AI schematic creator
The paper states the documentation pool can be updated without retraining, which is a significant practical advantage. How does DocPrompting manage situations where multiple versions of the same API might exist within the documentation, potentially causing confusion? AI zombie video creator
The documentation pool can be regularly updated without requiring costly retraining. How might the system differentiate between documentation for different versions of the same API if multiple are present? make Rumpelstiltskin video from photo
The framing here is the part worth keeping: the bottleneck is not model size but the fact that an unfamiliar library has documentation you can fetch at inference time. Treating the docs pool as updatable state instead of something baked into weights is also the more honest way to think about keeping a coding assistant current, since library APIs drift faster than any training cycle. The 1.65 BLEU gain on unseen Python functions is a modest number but a meaningful one, because it comes from exactly the cases that break in real work. One thing I would like to see tested is what happens when retrieved docs are version-mismatched for the same API, since a confident wrong signature is worse than no retrieval at all. On the generative side I have been following tools that apply the same bounded-inputs idea to consumer products, including Send The Song, which takes a recipient’s name, a shared memory and a short message and turns them into a private gift page with personalized lyrics, melody and vocals, with the lyric draft editable before generation and free credits at signup. Small constrained inputs, predictable outputs. Thanks for the clear writeup.
The point about models only generating code for libraries they’ve seen during training really captures the retrieval gap DocPrompting is trying to close by pulling in relevant documentation. That same retrieve-then-generate instinct is what drew me to Cliplumi Online for prompt-based photo editing, since it lets you add up to 3 references to steer the model. Curious how well the documentation retrieval holds up for more obscure or fast-changing libraries.
For those exploring innovative AI applications beyond code generation, there are platforms now making creative tasks much easier. If you need to quickly edit or generate images, or even create AI-powered videos, you might want to check out this all-in-one solution that’s free to start. It’s impressive how accessible advanced AI tools can be for both tech and creative work. Try it out here: edit image
Fascinating to see how innovations like DocPrompting are pushing the boundaries of code generation by smartly incorporating documentation retrieval. For those interested in exploring more advanced AI-powered creative tools—not just for code but also for editing photos, generating images, and creating AI videos—I highly recommend checking out nano banana. It’s a versatile platform powered by multiple models, free to start, and could be a valuable addition to anyone working with AI in different domains.
If you’re interested in how advanced AI models can bridge the gap between natural language prompts and complex outputs—just like DocPrompting does for code generation—you might want to check out Recraft v4. It leverages powerful AI models to turn text prompts into high-quality images, illustrations, and fully editable SVG vectors. Perfect for creators and marketers looking to streamline their visual content creation!
The approach first learns to retrieve relevant documents, then generates code. This two-step process seems more robust than trying to bake all documentation knowledge directly into the model’s weights. ai video generator from photo
Retrieving relevant documentation before generating code seems like a practical way to keep outputs grounded rather than relying only on memorized patterns. I can see this being useful for projects exploring web recomp games, where context-specific guidance could make experimentation much smoother.